Summary
- BreadthFirstPaths(or Breadth First Search BFS)
- Graph API
- Graph Representations and Graph Algorithm Runtimes
- Adjacency Matrix
- Edge Sets
- Adjacency Lists
- Graph Traversal Implementations and Runtimes
BreadthFirstPaths(or Breadth First Search BFS)


In Lecture 23, we developed DFS (Depth First Search) Traversal for graphs. In DFS, we visit down the entire lineage of our first child before we even begin to look at our second child - we literally search depth first.
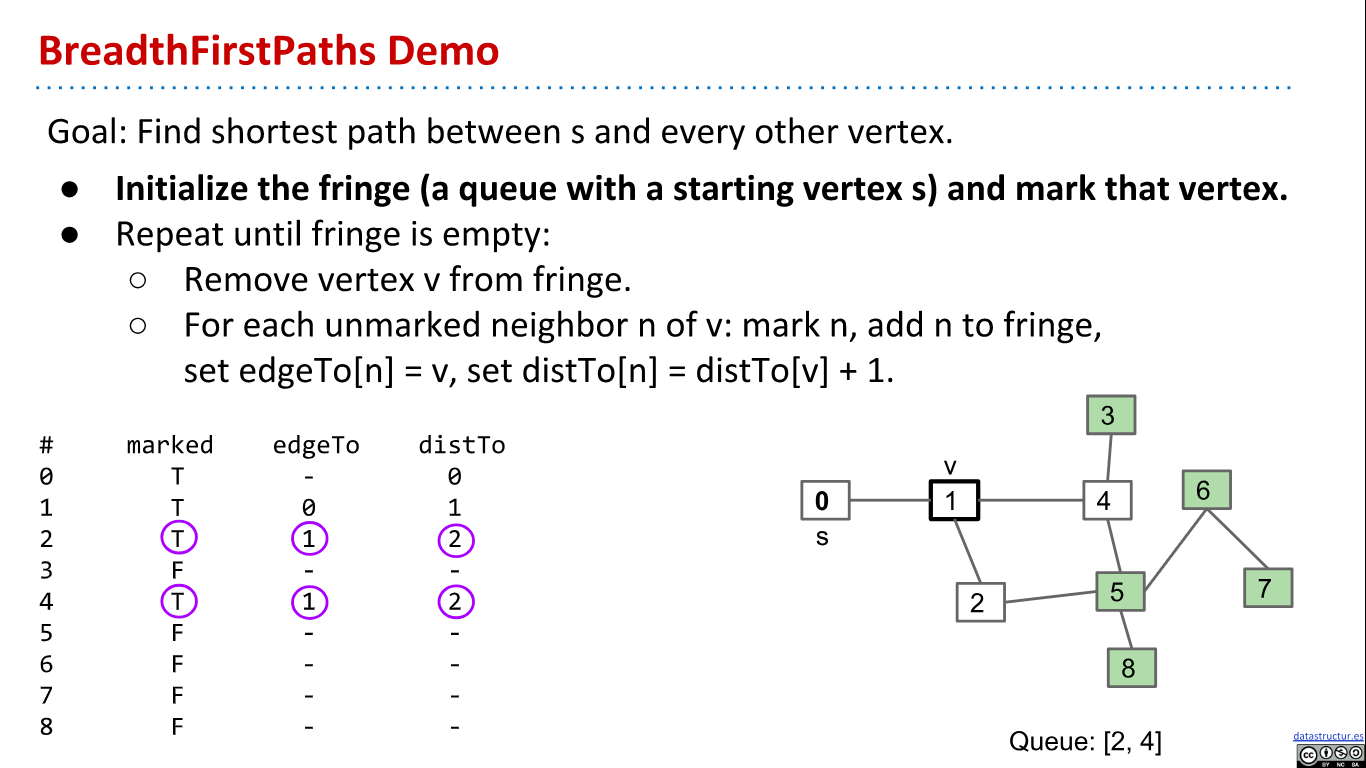
Here, we will talk about BFS (Breadth First Search) (also known as Level Order Traversal). In BFS, we visit all of our immediate children before continuing on to any of our grandchildren. In other words, we visit all nodes 1 edges from our source. Then, all nodes 2 edges from our source, etc.
The pseudocode for BFS is as follows:
Initialize the fringe (a queue with the starting vertex) and mark that vertex.
Repeat until fringe is empty:
Remove vertex v from the fringe.
For each unmarked neighbor n of v:
Mark n.
Add n to fringe.
Set edgeTo[n] = v.
Set distTo[n] = distTo[v] + 1.
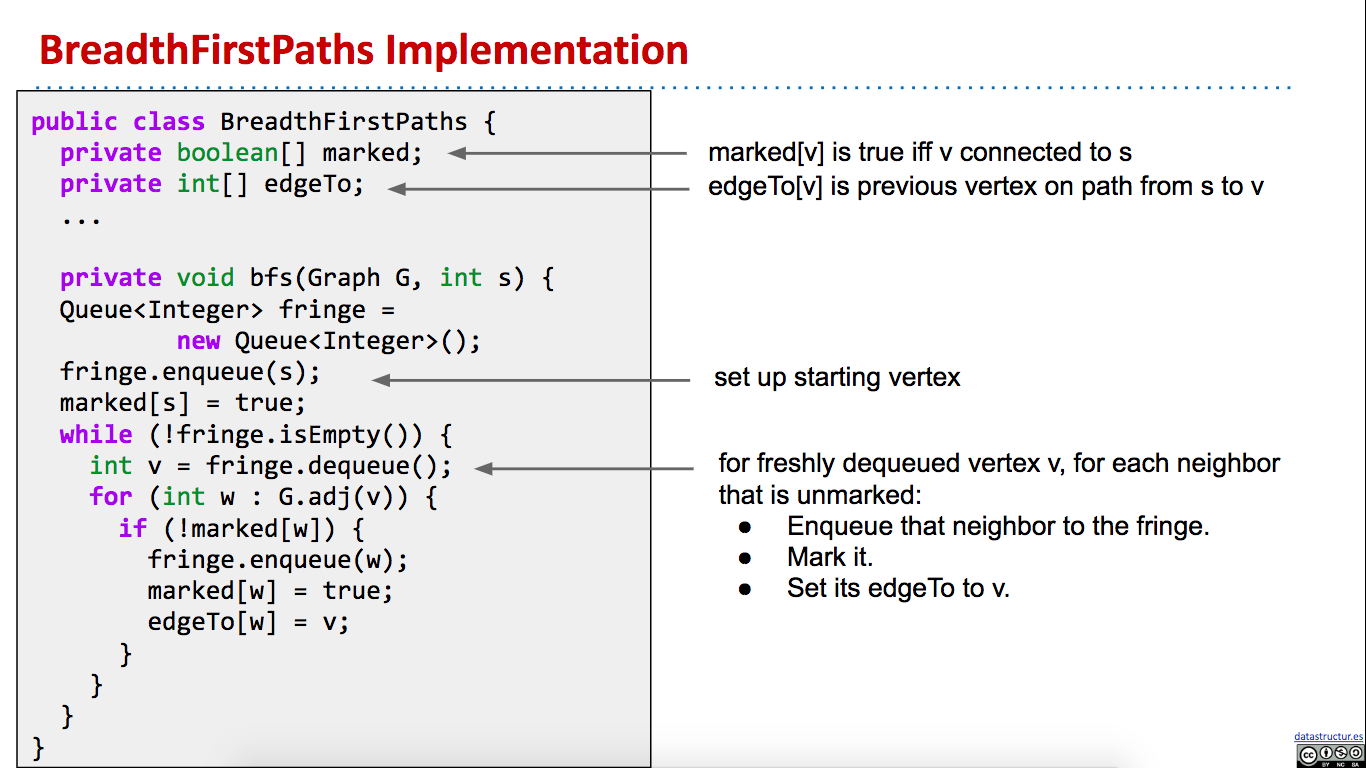
A fringe is just a term we use for the data structure we are using to store the nodes on the frontier of our traversal's discovery process (the next nodes it is waiting to look at). For BFS, we use a queue for our fringe.
edgeTo[...] is a map that helps us track how we got to node n; we got to it by following the edge from v to n.
distTo[...] is a map that helps us track how far n is from the starting vertex. Assuming that each edge is worth a distance of 1, then the distance to n is just one more than the distance to get to v. Why? We can use the way we know how to get to v, then pay one more to arrive at n via the edge that necessarily exists between v and n (it must exist since in the for loop header, n is defined as a neighbor of v).
BFS Demo
link



DFS vs BFS
Question 18.1: What graph traversal algorithm uses a stack rather than a queue for its fringe?
Answer 18.1: DFS traversal.
Note however that DFS and BFS differ in more than just their fringe data structure. They differ in the order of marking nodes. For DFS we mark nodes only once we visit a node - aka pop it from the fringe. As a result, it's possible to have multiple instances of the same node on the stack at a time if that node has been queued but not visited yet. With BFS we mark nodes as soon as we add them to the fringe so this is not possible.
Recursive DFS implements this naturally via the recursive stack frames; iterative DFS implements it manually:
Initialize the fringe, an empty stack
    push the starting vertex on the fringe
    while fringe is not empty:
        pop a vertex off the fringe
        if vertex is not marked:
            mark the vertex
            visit vertex
            for each neighbor of vertex:
                if neighbor not marked:
                    push neighbor to fringe
Graph API
We will discuss our choice of API, and also the underlying data structures used to represent the graph. Our decisions can have profound implications on our runtime, memory usage, and difficulty of implementing various graph algorithms.

An API (Application Programming Interface) is a list of methods available to a user of our class, including the method signatures (what arguments/parameters each function accepts) and information regarding their behaviors.
For our Graph API, let's use the common convention of assigning each unique node to an integer number. This can be done by maintaining a map which can tell us the integer assigned to each original node label. Doing so allows us to define our API to work with integers specifically, rather than introducing the need for generic types.

We can then define our API to look something like this perhaps:

Clients (people who wish to use our Graph data structure), can then use any of the functions we provide to implement their own algorithms. The methods we provide can have a significant impact on how easy/difficult it may be for our clients to implement particular algorithms.
Graph Representations and Graph Algorithm Runtimes
Next, we'll talk about the underlying data structures that can be used to represent our graph.

Just as we saw with trees, there are many possible implementations we could choose for our graphs.
Let's briefly review some representation we saw for trees.


Adjacency Matrix
One way we can do this is by using a 2D array. There is an edge connecting vertex s to t if that corresponding cell is 1 (which represents true). Notice that if the graph is undirected, the adjacency matrix will be symmetric across its diagonal (from the top left to the bottom right corners).


Edge Sets
Another way is to store a single set of all the edges.

Adjacency Lists
A third way is to maintain an array of lists, indexed by vertex number. If there is an edge from s to t, the list at array index s will contain t.
In practice, adjacency lists are most common since graphs tend to be sparse (there are not many edges in each bucket).


Efficiency


Graph Traversal Implementations and Runtimes
Depth First Path Demo in #107



Summary


Summary
BreadthFirstPaths(or Breadth First Search BFS)
In Lecture 23, we developed DFS (Depth First Search) Traversal for graphs. In DFS, we visit down the entire lineage of our first child before we even begin to look at our second child - we literally search depth first.
Here, we will talk about BFS (Breadth First Search) (also known as Level Order Traversal). In BFS, we visit all of our immediate children before continuing on to any of our grandchildren. In other words, we visit all nodes 1 edges from our source. Then, all nodes 2 edges from our source, etc.
The pseudocode for BFS is as follows:
A fringe is just a term we use for the data structure we are using to store the nodes on the frontier of our traversal's discovery process (the next nodes it is waiting to look at). For BFS, we use a queue for our fringe.
edgeTo[...]is a map that helps us track how we got to node n; we got to it by following the edge from v to n.distTo[...]is a map that helps us track how farnis from the starting vertex. Assuming that each edge is worth a distance of1, then the distance tonis just one more than the distance to get tov. Why? We can use the way we know how to get tov, then pay one more to arrive atnvia the edge that necessarily exists betweenvandn(it must exist since in the for loop header,nis defined as a neighbor ofv).BFS Demo
link
DFS vs BFS
Question 18.1: What graph traversal algorithm uses a stack rather than a queue for its fringe?
Answer 18.1: DFS traversal.
Note however that DFS and BFS differ in more than just their fringe data structure. They differ in the order of marking nodes. For DFS we mark nodes only once we visit a node - aka pop it from the fringe. As a result, it's possible to have multiple instances of the same node on the stack at a time if that node has been queued but not visited yet. With BFS we mark nodes as soon as we add them to the fringe so this is not possible.
Recursive DFS implements this naturally via the recursive stack frames; iterative DFS implements it manually:
Graph API
We will discuss our choice of API, and also the underlying data structures used to represent the graph. Our decisions can have profound implications on our runtime, memory usage, and difficulty of implementing various graph algorithms.
An API (Application Programming Interface) is a list of methods available to a user of our class, including the method signatures (what arguments/parameters each function accepts) and information regarding their behaviors.
For our Graph API, let's use the common convention of assigning each unique node to an integer number. This can be done by maintaining a map which can tell us the integer assigned to each original node label. Doing so allows us to define our API to work with integers specifically, rather than introducing the need for generic types.
We can then define our API to look something like this perhaps:

Clients (people who wish to use our Graph data structure), can then use any of the functions we provide to implement their own algorithms. The methods we provide can have a significant impact on how easy/difficult it may be for our clients to implement particular algorithms.
Graph Representations and Graph Algorithm Runtimes
Next, we'll talk about the underlying data structures that can be used to represent our graph.
Just as we saw with trees, there are many possible implementations we could choose for our graphs.
Let's briefly review some representation we saw for trees.


Adjacency Matrix
One way we can do this is by using a 2D array. There is an edge connecting vertex
stotif that corresponding cell is1(which representstrue). Notice that if the graph is undirected, the adjacency matrix will be symmetric across its diagonal (from the top left to the bottom right corners).Edge Sets
Another way is to store a single set of all the edges.
Adjacency Lists
A third way is to maintain an array of lists, indexed by vertex number. If there is an edge from
stot, the list at array indexswill containt.In practice, adjacency lists are most common since graphs tend to be sparse (there are not many edges in each bucket).
Efficiency
Graph Traversal Implementations and Runtimes
Depth First Path Demo in #107


Summary