Part of Speech (POS) tagging assigns grammatical labels such as nouns, verbs, adjectives, and adverbs to words in a sentence. NLTK provides functions for POS tagging and a predefined list of English stop words that can be used to filter common words during text preprocessing.
By combining these features, we can identify the grammatical roles of words and remove unwanted tokens while retaining useful linguistic information.
Installation
Open your terminal or command prompt and run the following command to install NLTK:
pip install nltk
Import NLTK and download required packages:
import nltk
nltk.download()
Quick Vocabulary
- Corpus: A body of text. Plural: corpora.
- Lexicon: Words and their meanings.
- Token: A single unit in a text, often a word or punctuation.
1. Define Input Text and Tokenize
Create a sample sentence and split it into individual tokens using word_tokenize().
text = "The quick brown fox jumps over the lazy dog and runs in the park."

tokens = word_tokenize(text)

print("Original Tokens:")
print(tokens)
Output
Original Tokens:
['The', 'quick', 'brown', 'fox', 'jumps', 'over', 'the', 'lazy', 'dog', 'and', 'runs', 'in', 'the', 'park', '.']
Explanation:
- text variable stores the input sentence.
- word_tokenize() separates the sentence into words and punctuation marks.
- Keeping punctuation during tokenization allows us to inspect the original sentence structure before filtering.
2. Loading Stop Words
Load NLTK's predefined English stop-word list and convert it into a set for efficient membership checking.
stop_words = set(stopwords.words('english'))

print("Sample Stop Words:")
print(list(stop_words)[:10])
Output
Sample Stop Words:
['the', 'is', 'and', 'in', 'to', 'of', 'a', 'for', 'on', 'with']
Explanation:
- stopwords.words('english') retrieves commonly used English stop words.
- set() converts the list into a set, making repeated membership checks efficient.
- Predefined list can be extended or customized according to the requirements of a particular NLP task.
4. Performing POS Tagging
Apply POS tagging to the original tokens before removing stop words. This preserves the surrounding linguistic context when assigning grammatical labels.
tagged_words = pos_tag(tokens)

print("POS Tagged Words:")
print(tagged_words)
Output
POS Tagged Words:
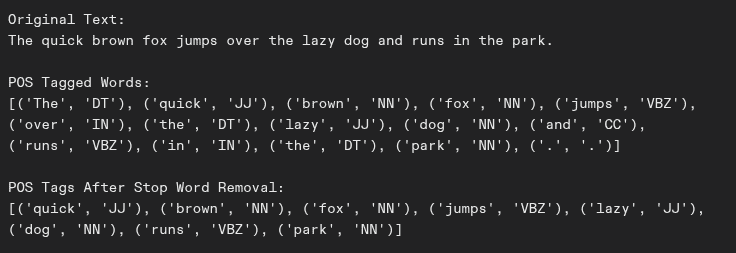
[('The', 'DT'), ('quick', 'JJ'), ('brown', 'JJ'), ('fox', 'NN'), ('jumps', 'VBZ'), ('over', 'IN'), ('the', 'DT'), ('lazy', 'JJ'), ('dog', 'NN'), ('and', 'CC'), ('runs', 'VBZ'), ('in', 'IN'), ('the', 'DT'), ('park', 'NN'), ('.', '.')]
Explanation:
- pos_tag() returns a list of tuples containing each token and its corresponding grammatical tag.
- DT represents a determiner, JJ an adjective, NN a singular noun, and VBZ a third-person singular present-tense verb.
- IN represents a preposition, CC a coordinating conjunction, and a period is represented by the punctuation tag.
- Each tag describes how a word functions in the original sentence.
5. Removing Stop Words from Tagged Output
Filter out stop words and punctuation while preserving the remaining words and their POS tags.
filtered_tagged_words = [
    (word, tag)
    for word, tag in tagged_words
    if word.lower() not in stop_words and word.isalpha()
]

print("POS Tags After Stop Word Removal:")
print(filtered_tagged_words)
Output
POS Tags After Stop Word Removal:
[('quick', 'JJ'), ('brown', 'JJ'), ('fox', 'NN'), ('jumps', 'VBZ'), ('lazy', 'JJ'), ('dog', 'NN'), ('runs', 'VBZ'), ('park', 'NN')]
Explanation:
- List comprehension processes each word-tag pair returned by post_tag().
- word.lower() makes stop-word matching case-insensitive, so words such as "THE" and "The" are handled consistently.
- Condition excludes words found in the stop-word set.
- word.isalpha() remove punctuation and other tokens that are not purely alphabetic.
- Original POS tags remain associated with their word after filtering.
Complete Program
Following program combines tokenization, POS tagging, and stop-word removal into one implementation.
import nltk
from nltk.corpus import stopwords
from nltk.tokenize import word_tokenize
from nltk import pos_tag

nltk.download('punkt_tab')
nltk.download('averaged_perceptron_tagger_eng')
nltk.download('stopwords')

text = "The quick brown fox jumps over the lazy dog and runs in the park."

tokens = word_tokenize(text)

stop_words = set(stopwords.words('english'))

tagged_words = pos_tag(tokens)

filtered_tagged_words = [
    (word, tag)
    for word, tag in tagged_words
    if word.lower() not in stop_words and word.isalpha()
]

print("Original Text:")
print(text)

print("\nPOS Tagged Words:")
print(tagged_words)

print("\nPOS Tags After Stop Word Removal:")
print(filtered_tagged_words)
Output: